Full-stack RAG · Qdrant vector search · 2025
K-Drama RAG Engine
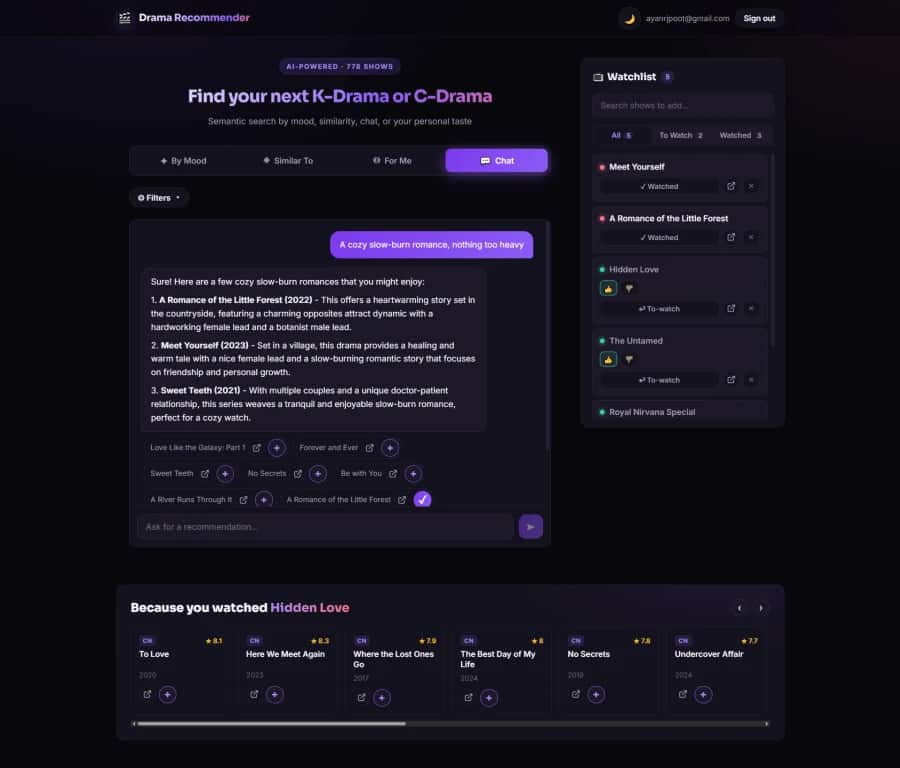
A production RAG recommendation engine: Qdrant vector search over 838 self-scraped dramas, an ONNX cross-encoder reranker that cut backend memory roughly 4×, and GPT-4o grounded strictly in retrieved evidence.
Visit the store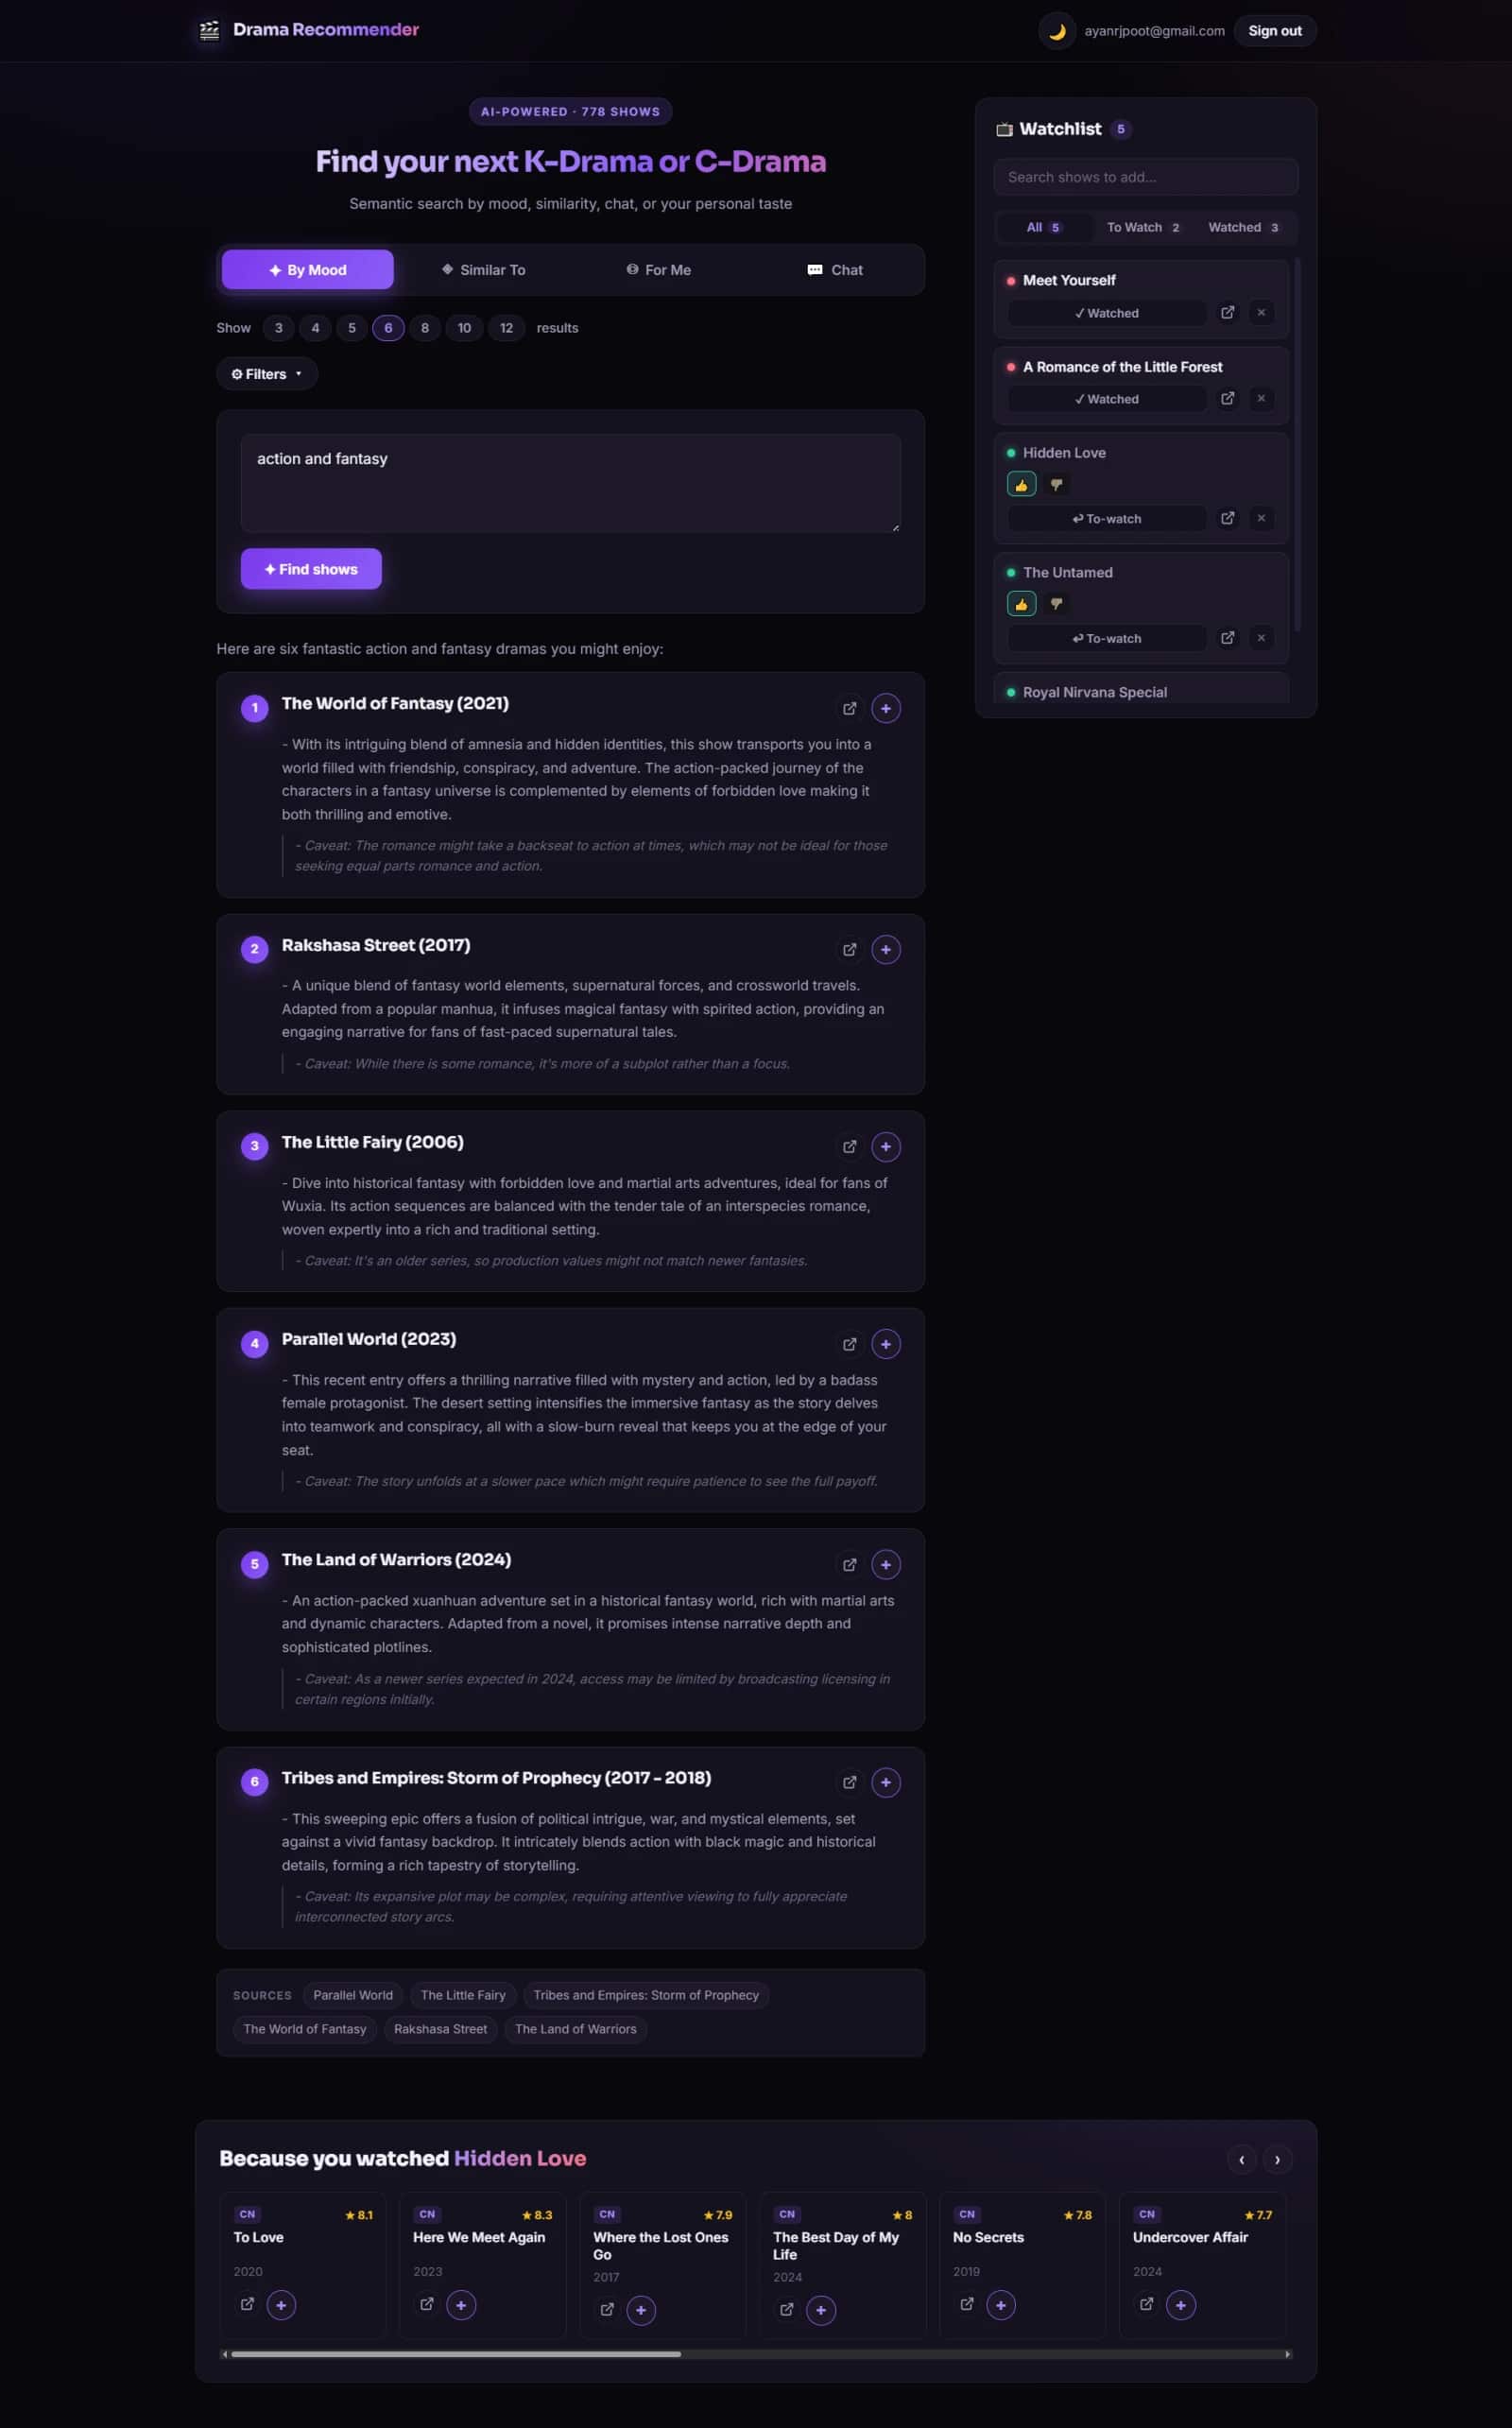
Problem
Recommending dramas from natural-language queries ("cozy and emotional, not too heavy") needs to match meaning, not keywords — and an LLM left to its own knowledge happily invents shows that don't exist. Serving the cross-encoder reranker in PyTorch then pushed the backend into an out-of-memory crash-loop in production.
Solution
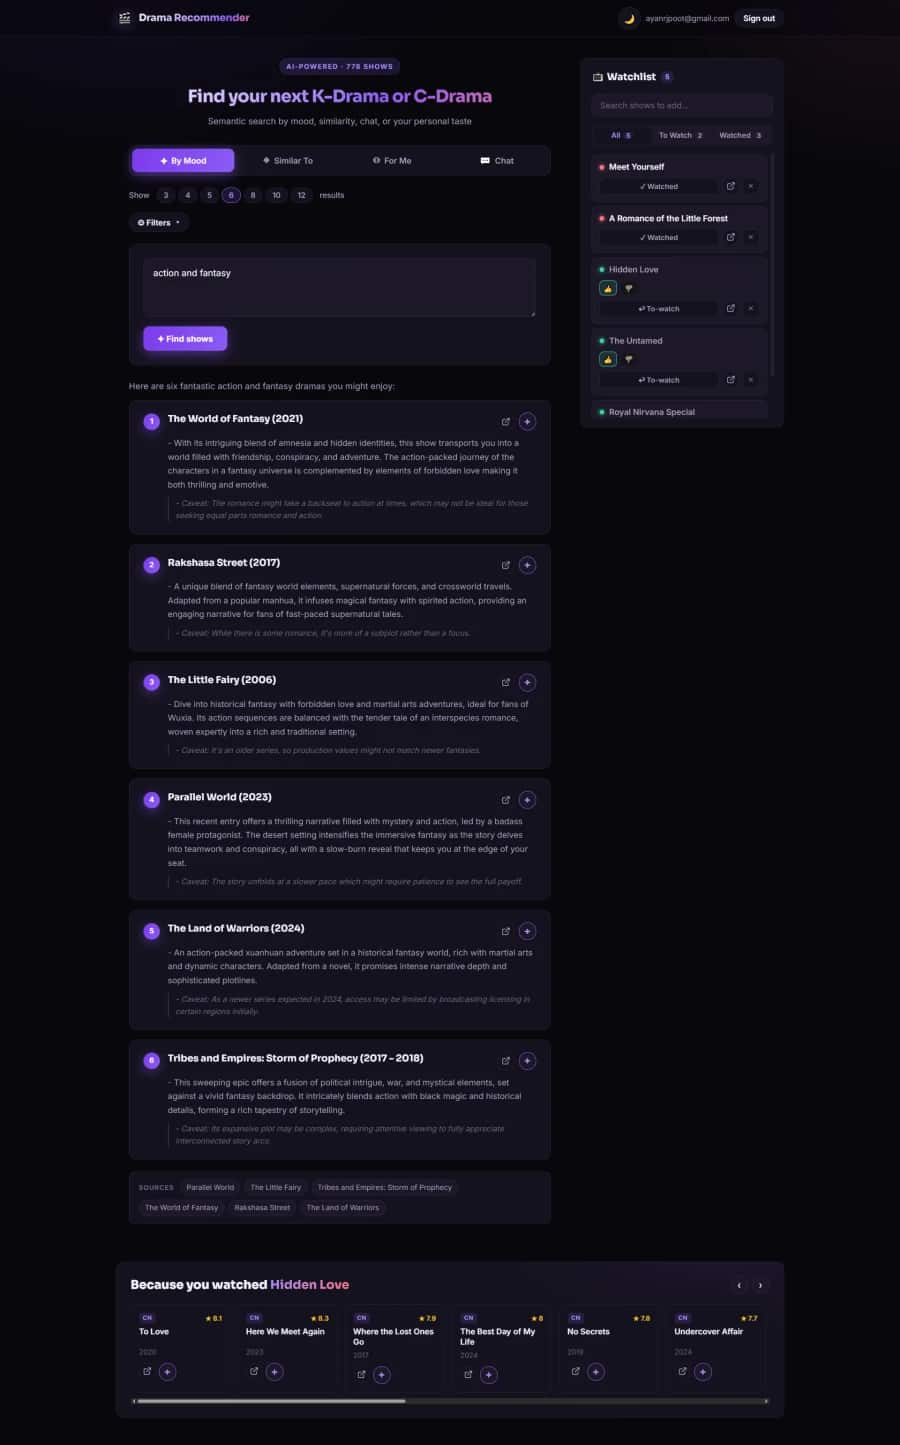
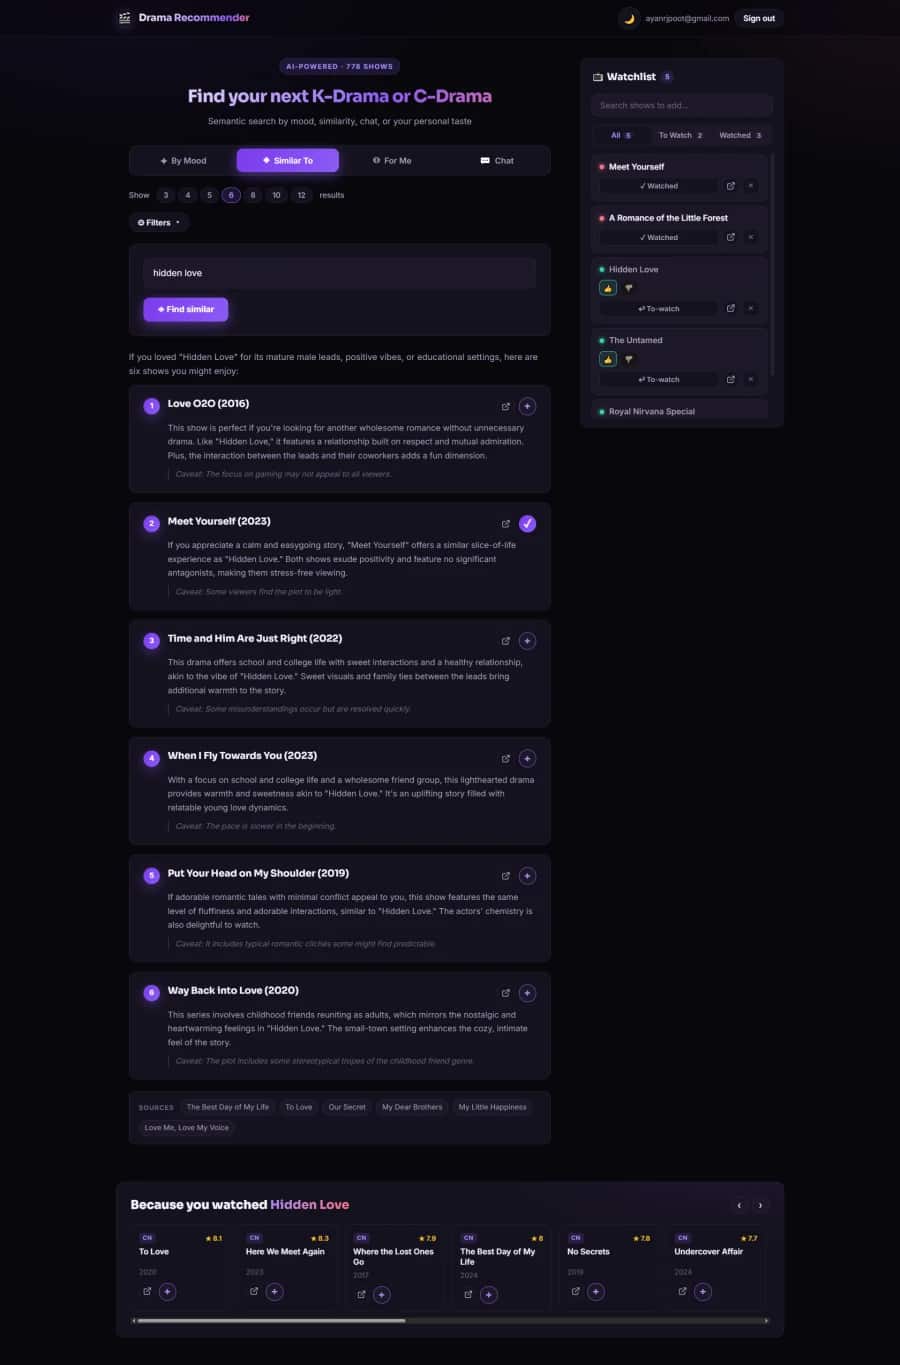
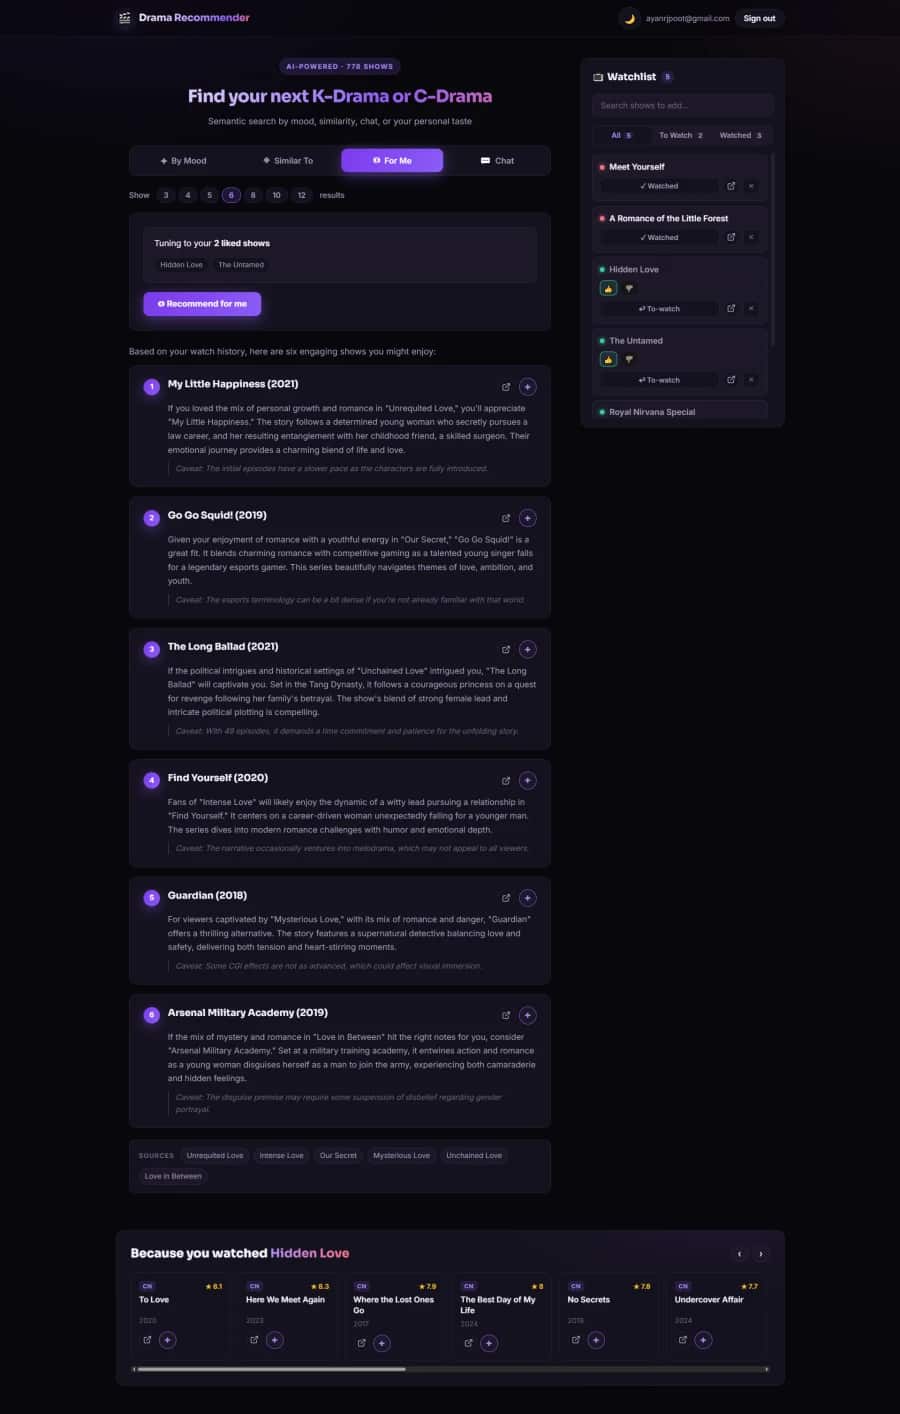
838 dramas are embedded into a 1,536-d space (OpenAI) and split into four typed chunks — synopsis, mood, review, similarity — so each query intent stays sharp instead of averaged into mush. Qdrant ANN recalls ~30 candidates, an ONNX cross-encoder reranks to the top 6, and GPT-4o explains the picks grounded only in the retrieved shows (surfaced back via an X-Sources header). Four modes (mood, similarity, personalized, chat), token streaming, metadata filters, and a Supabase watchlist with a ratings feedback loop. Deployed across Vercel, Railway and Qdrant Cloud.
Result
~$0.01 per query. Serving the cross-encoder reranker on ONNX Runtime instead of PyTorch cut backend memory roughly 4× (≈800 MB → ≈200 MB) with the same weights and zero quality loss — which fixed the production OOM crash-loop and brought the whole system inside free-tier hosting. Personalization is pure vector arithmetic over liked/disliked embeddings: no model training.
Built with
- RAG
- Vector search
- Qdrant
- OpenAI
- FastAPI
- React
- Supabase
- ONNX
- Python